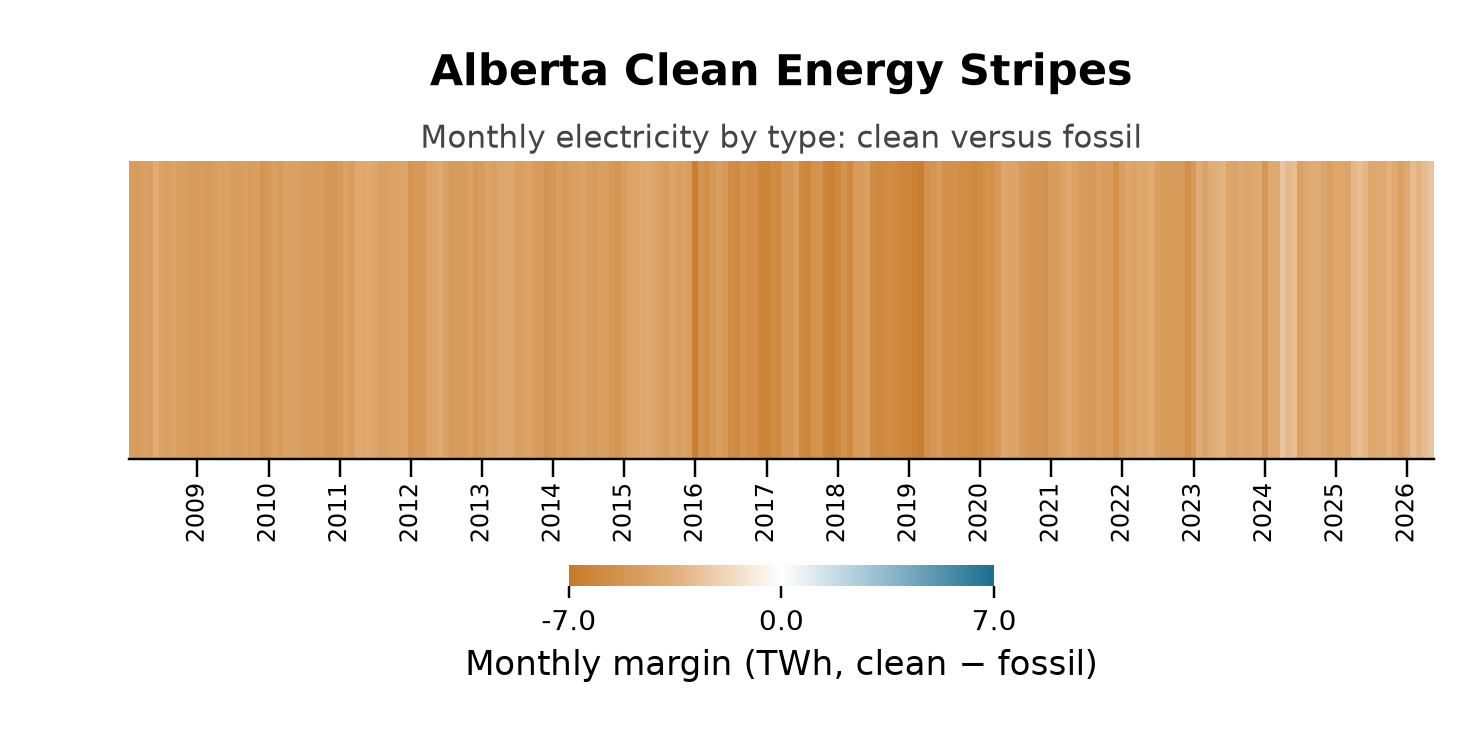
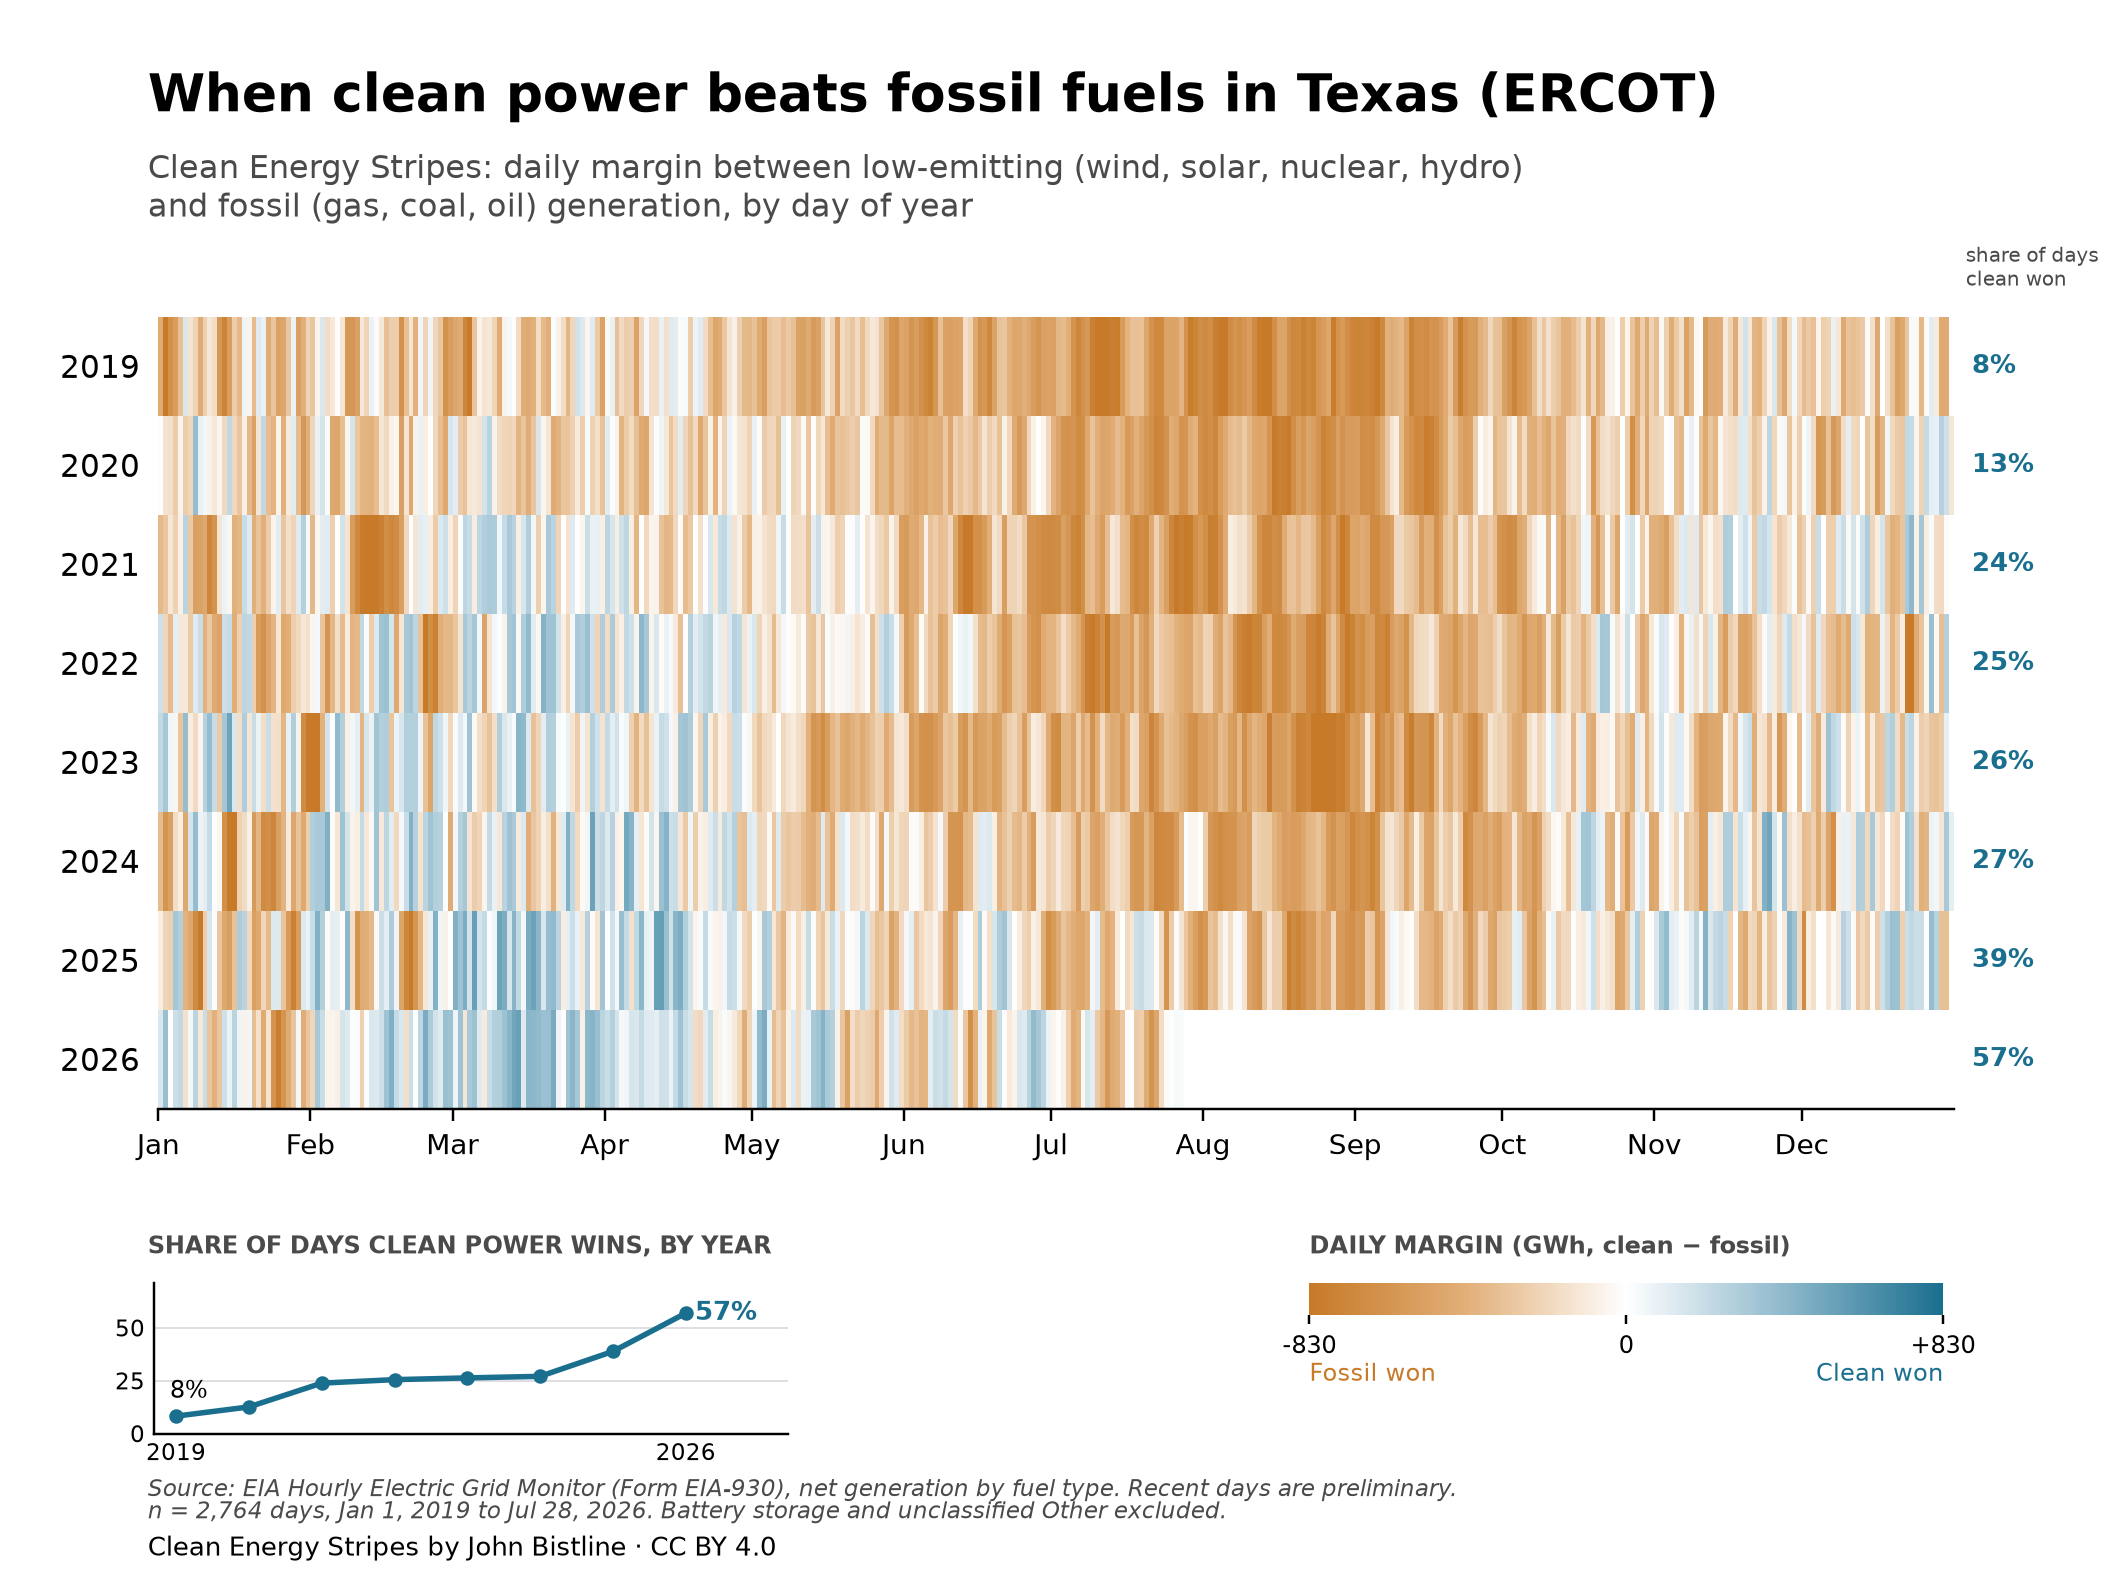
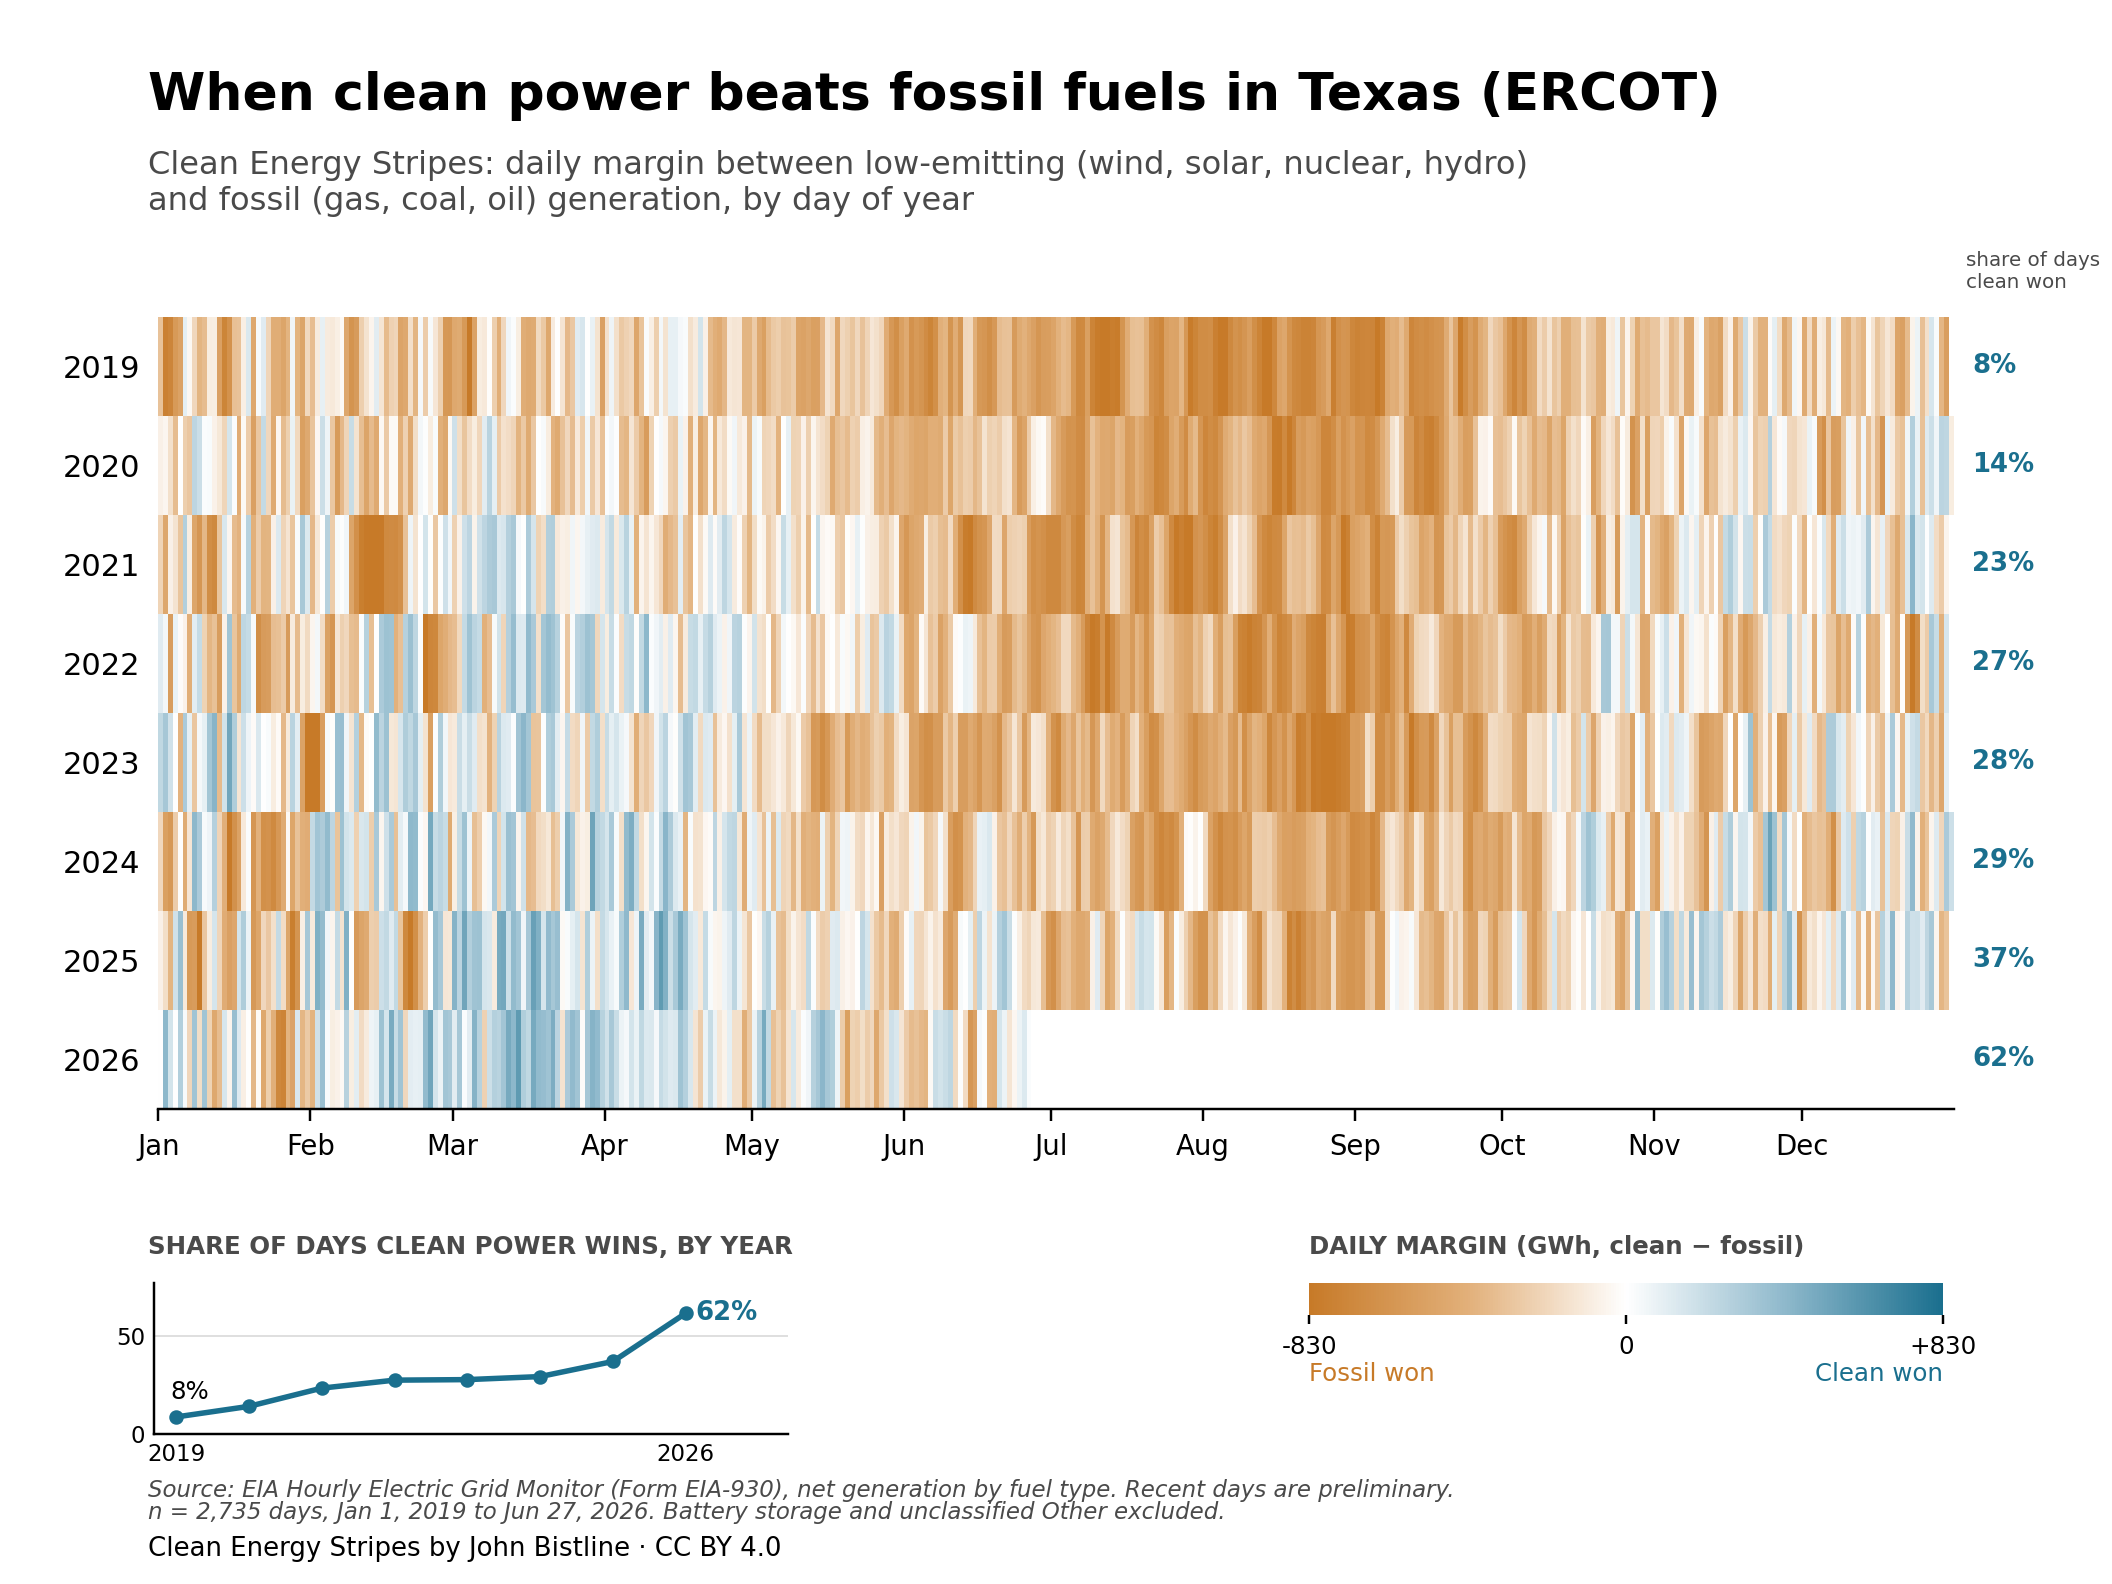
Alberta is often described as Canada’s Texas. And the description fits in many ways. One policy area in which the two have diverged is in the adoption of renewable energy for electricity production. Whereas Texas has become (seemingly overnight) a renewable energy powerhouse, Alberta (under its UCP Premier, Danielle Smith) has decided to double-down on fossil fuels. The charts below visually represent this divergence in policy. See my previous post to understand how to interpret these charts.
A quick reminder: the more dark orange is the vertical stripe for that particular month (Alberta) or day (Texas), the greater is the difference in the amount of electricity produced by fossil fuels versus renewable (“clean”) energy. We can see that Alberta’s mix of electricity production is still dominated by fossil fuels (although the stripes are trending less orange over time). Contrast that to Texas, where renewables (“clean”) are producing a majority of electricity each day over the last year or so. The question, though, is: “who is taking the road less traveled?”
Note that to the point in 2026 when the Texas chart was created, renewables had “won the day” in terms of producing more electricity than fossil fuels, 57% of the time. That’s impressive in a state that has traditionally tethered its electricity production to the its massive repository of fossil fuel.
I’ll be using this website to create a catalogue of what I consider to be important data visualizations in the general knowledge area of climate change/climate science.
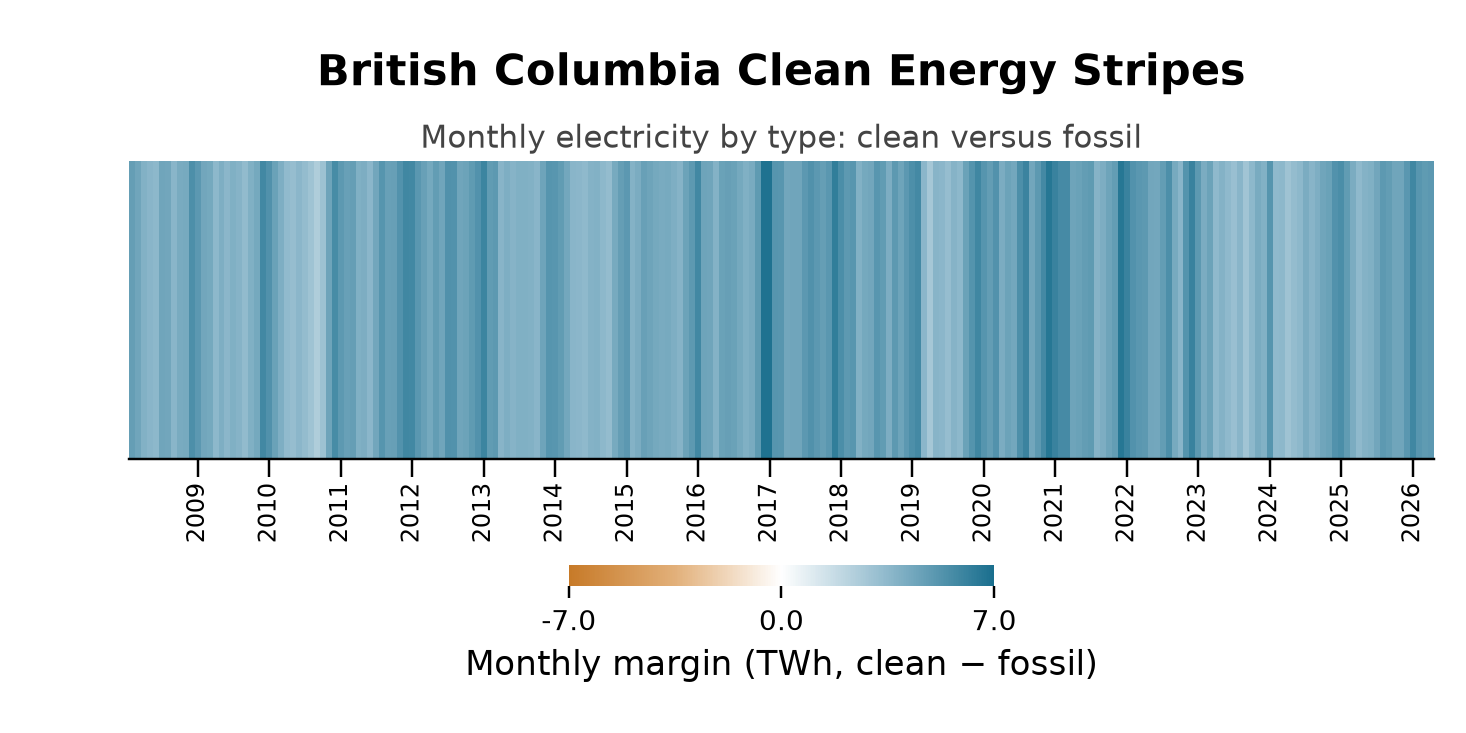
Here is the first visualization, which looks at the the sources of electricity production in the Canadian province of British Columbia. With the exception of a couple of provinces (Alberta and Saskatchewan, primarily), sources of Canadian electricity production are overwhelmingly fossil fuel-free. The predominant type of energy production is hydroelectric, which has traditionally been supplemented by nuclear power. In recent years, wind and solar energy sources have come online and continue to increase their output on an annual basis.
Using python code developed by John Bistline as a baseline, I have created a chart that shows the relative monthly amounts of “clean” versus “fossil fuel” electricity production in British Columbia since 2008. Bistline’s charts use daily totals, but I couldn’t find daily data for BC, so I am using monthly data.
How does one interpret this chart? The darker the blue, the greatest is the absolute difference (in TWh–terawatt-hours) between the monthly output of ‘clean’ (i.e., renewable) electricity and produced from the burning of fossil fuels. The darkest blue bars (they are monthly bars) reflect that in that particular month about 6 more TWh of clean electricity were produced than that from fossil fuels.
It’s interesting to note that there doesn’t seem to be any secular trend over time; that is, it’s not apparent that more relative electricity of either type is being produced over time. We do see some seasonal fluctuations. For example, summers seem to be marked by much lower differences in the relative output of clean-versus-fossil fuel electricity production. We can contrast this with the USA state of Texas, which clearly demonstrates a surge in the relative amount of clean electricity produced over time. Texas may be a fossil fuel energy powerhouse, but it is increasingly becoming a clean energy powerhouse as well (see chart below). We can contrast this with the situation in Alberta, which is the topic of a future chart (the chart will be mostly orange).
Note: these are daily data.
License & reuse
Clean Energy Stripes are released under a Creative Commons Attribution 4.0 license, in the spirit of Ed Hawkins’ original warming stripes. You are free to share and adapt them — make your own with national or subnational data, and credit “John Bistline, Clean Energy Stripes / Data: EIA-930.”
In data visualization posts #21 and #22, I referred to the results of simple multivariate linear regressions where I examined the statistical relationships between the cost of electricity across European Union countries and the market penetration of renewable energy sources, and a cost-of-living index. Here are the regression results that form the source data for the predictive plots in those blog posts.
First, with the price of electricity as the dependent variable (DV):
## Here is the R code for the linear regression (using the generalized linear models (glm) framework:
glm.1<-glm(Elec_Price~COL_Index+Pct_Share_Total,data=eu.RENEW.only,family="gaussian")  # Electricity Price is DV


MODEL INFO:
Observations: 28
Dependent Variable: Price of Household Electricity (in Euro cents)
Type: Linear regression

MODEL FIT:
χ²(2) = 306.82, p = 0.00
Pseudo-R² (Cragg-Uhler) = 0.40
Pseudo-R² (McFadden) = 0.08
AIC = 166.04, BIC = 171.37

Standard errors: MLE
-------------------------------------------------------------
                                 Est.   S.E.   t val.      p
------------------------------ ------ ------ -------- ------
(Intercept)                     4.10   3.59     1.14   0.26
Cost-of-Living Index            0.22   0.06     3.59   0.00
Renewables (% share of total)   0.03   0.04     0.74   0.46
-------------------------------------------------------------
We can see that the cost-of-living index is positively correlated with the price of household electricity, and it is statistically significant at conventional (p=0.05) levels. The market penetration of renewables (on the other hand) is not statistically significant (once controlling for cost-of-living.
Now, we use the pre-tax price of electricity (there are large differences in levels of taxation of household electricity across EU countries) as the DV. Here are the regression code (R) and the model results of the multivariate linear regression.
## Here is the R code for the linear regression (using the generalized linear models (glm) framework:

glm.2<-glm(Elec_Price_NoTax~COL_Index+Pct_Share_Total,data=eu.RENEW.only,family="gaussian")  # Elec Price LESS taxes/levies is DV


MODEL INFO:
Observations: 28
Dependent Variable: Pre-tax price of Household Electricity (Euro cents)
Type: Linear regression

MODEL FIT:
χ²(2) = 100.13, p = 0.00
Pseudo-R² (Cragg-Uhler) = 0.44
Pseudo-R² (McFadden) = 0.12
AIC = 130.11, BIC = 135.43

Standard errors: MLE
-------------------------------------------------------------
                                 Est.   S.E.   t val.      p
-----------------------------  ------- ------ -------- ------
(Intercept)                      5.20   1.89     2.75   0.01
Cost-of-Living Index             0.14   0.03     4.41   0.00
Renewables (% share of total)   -0.03   0.02    -1.44   0.16
-------------------------------------------------------------
Here, we see an even stronger relationship between the cost-of-living and the pre-tax price of household electricity, while there is (once the cost-of-living is controlled for) a negative (though not quite statistically significant) relationship between the pre-tax cost of electricity and the market penetration of renewables across EU countries.
One of the first things that is (or should be) taught in a quantitative methods course is that “correlation is not causation.” That is, just because we establish that a correlation between two numeric variables exists, that doesn’t mean that one of these variables in causing the other, or vice versa. And to step back ever further in our analytical process, even when we find a correlation between two numerical variables, that correlation may not be “real.” That is, it may be spurious (caused by some third variable) or an anomaly of random processes.
I’ve seen the chart below (in one form or another) for many years now and it’s been used by opponents of renewable energy to support their argument that renewable energy sources are poor substitutes for other sources (such as fossil fuels) because, amongst other things, they are more expensive for households.
In this example, the creators of the chart seem to show that there is a positive (and non-linear) relationship between the percentage of a European country’s energy that is supplied by renewables and the household price of electricity in that country. In short, the more a country’s energy grid relies on renewables, the more expensive it is for households to purchase electricity. And, of course, we are supposed to conclude that we should eschew renewables if we want cheap energy. But is this true?
No. To reiterate, a bivariate (two variables) relationship is not only not conclusive evidence of a statistical relationship truly existing between these variables, but we don’t have enough evidence to support the implied causal story–more renewbles equals higher electricity prices.
Even a casual glance at the chart above shows that countries with higher electricity prices are also countries where the standard (and thus, cost) of living is higher. Lower cost-of-living countries seem to have lower electricity prices. So, how do we adjudicate? How do we determine which variables–cost-of-living, or renewables penetration–is actually the culprit for increased electricity prices?
In statistics, we have a tool called multiple regression analysis. It is a numerical method, in which competing variables “fight it out” to see which has more impact (numerically) on the variation in the dependent (in this case, cost of electricity) variable. I won’t get into the details of how this works, as it’s complicated. But it is a standard statistical method.
So, what do we notice when we perform a multivariate linear regression analysis (note: a non-linear method actually strongly the case below even more strongly, but we’ll stick to linear regression for ease of interpretation and analysis) where we “control for” each of the two independent variables–cost-of-living and renewables penetration)?
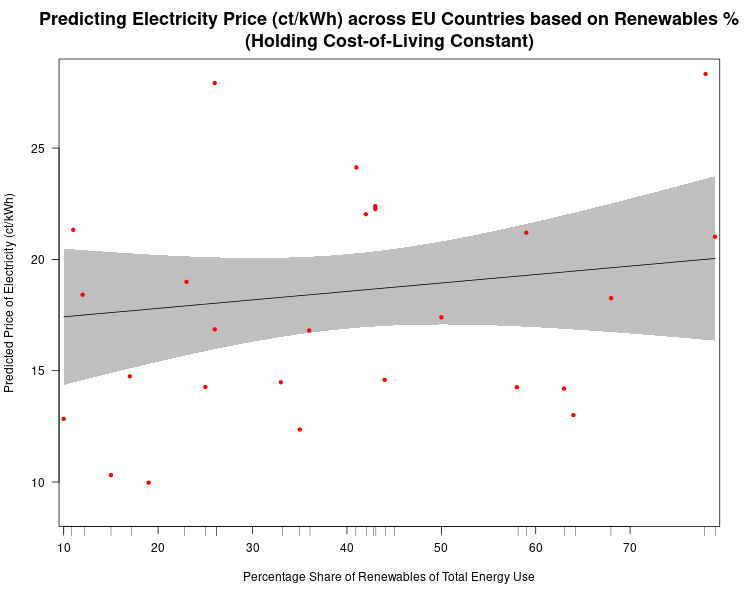
The image below shows (contrary to the implied claim in the chart above) that once we a country’s cost of living, there is little influence on the price of household electricity of renewables penetration in a country Moreover, the impact is not “statistically significant (see table at the end of the post).” That is, based on the data it is highly likely that the weak relationship we do see is simply due to random chance. We see this weak relationship in the chart below, which is the predicted cost of electricity in each country based on different levels of renewables penetration, holding the cost-of-living constant.
Created by: Josip Dasović
At only 10% of renewable penetration in a country the predicted price of electricity is about 17.5 ct/kWh (the shaded grey areas are 95% confidence bands, so we see that even though our best estimate of the price of electricity for a country that gets only 10% of its energy from renewables is 17.5 ct/kWh, we would expect the actual result to be between 14.5 ct/kWh and 20.5 ct/kWh 95% of the time. Our best estimate of the predicted cost of electricity in a country that gets 80% of its energy from renewables is expected to be about 19.5 ct/kWh. So, an 800% increase in renewables penetration leads only to only a 14.5% increase in the predicted price of electricity.
Now, what if we plot the predicted price of household electricity based on the cost-of-living after controlling for renewables penetration in a country? We see that, in this case, there is a much stronger relationship, which is statistically significant (highly unlikely for these data to produce this result randomly).
There are two things to note in the chart above. First, the 95% confidence bands are much closer together indicating much more certainty that there is a true statistical relationship between the “Cost-of-Living Index (COL)” and the predicted price of household electricity. And, we see that a 100% increase in the COL leads to a ((15.5-9.3)/9.3)*100%, or 67% increase in the predicted price of electricity in any EU country. (Note: I haven’t addressed the fact that electricity prices are a component of the COL, but they are so insignificant as to not undermine the results found here.
Stay tuned for the next post, where I’ll show that once we take out taxes and levies the relationship between the predicted price of household electricity and the penetration of renewables in an EU country is actually negative.
Here is the R code for the regression analyses, the prediction plots, and the table of regression results.
## This is the linear regression.
reg1<-lm(Elec_Price~COL_Index+Pct_Share_Total,data=eu.RENEW.only)

library(stargazer)  # needed for prediction cplots

## Here is the code for the two prediction plots.
## First plot
cplot(reg1,"COL_Index", what="prediction", main="Cost-of-Living Predicts Electricity Price (ct/kWh) across EU Countries\n(Holding Share of Renewables Constant)", ylab="Predicted Price of Electricity (ct/kWh)", xlab="Cost-of-Living Index")

## Second plot
cplot(reg1,"Pct_Share_Total", what="prediction", main="Share of Renewables doesn't Predict Electricity Price (ct/kWh) across EU Countries\n(Holding Cost-of-Living Constant)", ylab="Predicted Price of Electricity (ct/kWh)", xlab="Percentage Share of Renewables of Total Energy Use")
The table below was created in LaTeX using the fantastic stargazer (v.5.2.2) package created for R by Marek Hlavac, Harvard University. E-mail: hlavac at fas.harvard.edu
In my previous post I noted that I would provide python code for the chart that is in the post. The chart was created using R statistical software, and the code for the python version can be found at the end of this post.
I find python a bit less intuitive than R but that’s most likely because I’ve been using R for a very long time and python for less long. There are reasons, I suppose, to favour one over the other, but for statistical analysis and data analysis I don’t necessarily see an advantage of one over the other. That being said, it is my sense that R does a better job of standardizing across various operating systems, which can be very helpful when you are a Linux user, as am I.
import numpy as np
import matplotlib.pyplot as plt
import networkx as nx
from matplotlib.animation import FuncAnimation
plt.style.use('ggplot') # this is to make the plot look like an R ggplot

# a roulette array
roulette = np.append(np.array([0, 0]),np.arange(1, 37))
spins1000 = np.array(np.random.choice(roulette, size=(1000)))

# Define a cumulative mean function
def cum_mean(arr):
    cum_sum = np.cumsum(arr)
    return cum_sum / (np.arange(1, cum_sum.shape[0] + 1))     # as far as I can tell, matplotlib doesn't have a cumulative mean function; so I created one.


fig = plt.figure()
ax1 = fig.add_subplot(2, 1, 2)
ax2 = fig.add_subplot(2, 1, 1)
fig.tight_layout(pad=3.0)
fig.suptitle('Short-term Randomness versus Long-term Predictability', fontsize=14)
ax2.set_xlabel('$n^th$ spin of roulette wheel')
ax2.set_ylabel('Value of $n^{th}$ spin')
ax2.set_xlim(0, 1000)
ax2.set_ylim(0, 37)

ax1.set_xlabel('$n^{th}$ spin of the roulette wheel')
ax1.set_ylabel('Cumulative mean of n spins')
ax1.set_xlim(0, 1000)
ax1.set_ylim(0, 37)

line, = ax1.plot([], [], lw=1.5)
scat, = ax2.plot([], [], 'o', markersize=2)

def init():
    line.set_data([], [])
    scat.set_data([], [])
    return line, scat,

def animate(i):
    x = np.linspace(0, 250, 250)
    y1 = cum_mean(spins1000)
    y2 = spins1000
    line.set_data(x[:i], y1[:i])
    scat.set_data(x[:i], y2[:i])
    return line, scat,

anim = FuncAnimation(fig, animate, init_func=init, frames=1000, interval=10, blit=True, save_count=1000)

plt.show()

anim.save('roullete_python.mp4') # saving as .mp4 because python creates massive gif files.
In the most recent post in my data visualization series I made an analogy between climate, weather and the spins of a roulette wheel that demonstrated that short-term randomness does not mean we can’t make accurate long-term predictions.
Towards the end of the post I appended an animation of 1000 random spins of a roulette wheel. In that post, I plotted the 1000 individual outcomes of these random spins of the roulette wheel. I chose to show only one outcome at a time as the animation cycled through all 1000 spins. In this post, I wanted to show you how to keep all of the outcomes from disappearing. Rather than having the value of each spin appear, and then disappear, I will change the code slightly to have every spin’s outcome stay on the plot, but faded so that the focus remains on the next spin value. Here’s what I mean.:
Created by Josip Dasović
Here is the R code for the image above:
## These are the packages needed to draw, and animate, the plots.
library(ggplot2)
library(gganimate)
library(dplyr)  # needed for cummean function

## Set up a data frame for the 1000 random spins of the roulette wheel

mywheel <-c(rep(0,2),1:36)  # a vector with the 38 wheel values
wheel.df<-data.frame("x"=1:1000,"y"=sample(mywheel,1000,rep=T))

## Plot, then animate the result of 1000 random spins of the wheel

## the code to plot
gg.roul.1000.point<- ggplot(wheel.df,aes(x, y, colour = "firebrick4")) +
  geom_point(show.legend = FALSE, size=2) +
  theme_gray() +
  labs(title = "1000 Random Spins of a Roulette Wheel",
       x = expression("the"~n^th~"roll of the wheel"),
       y = 'Value of a single spin') +
  theme(plot.title = element_text(hjust = 0.5, size = 14, color = "black")) +
  scale_y_continuous(expand = c(0, 0)) +
  transition_time(wheel.df$x) +
  shadow_mark(past = T, future=F, alpha=0.2)

## the code to animate
gg.roul.anim.point <- animate(gg.roul.1000.point, nframes=500, fps=25, width=500, height=280, renderer=gifski_renderer("gg_roulette_1000.gif"))

## No plot and animate a line chart that depicts the cumulative mean from spin 1 to spin 1000.

gg.roul.1000.line <- ggplot(wheel.df, aes(x, y = cummean(y))) +
  geom_line(show.legend = FALSE, size=1, colour="firebrick4") +
  theme_gray() +
  ggtitle("Cumulative Mean of Roulette Wheel Spins is Stable over Time") +
  theme(plot.title = element_text(hjust = 0.5, size = 14, color = "black")) +
  labs(x = expression("the"~n^th~"roll of the wheel"),
       y = 'Running (i.e., cumulative) Mean of all Rolls at Roll n') +
  scale_y_continuous(expand=c(0,0), limits=c(0,36)) +
  transition_reveal(wheel.df$x) +
  ease_aes('linear')

gg.roul.anim.line <- animate(gg.roul.1000.line, nframes=500, fps=25, width=500, height=280, renderer=gifski_renderer("cummean_roulette_1000.gif"))

## Now combine the plots into one figure, using the magick library

library(magick)

a_mgif <- image_read(gg.roul.anim.point)
b_mgif <- image_read(gg.roul.anim.line)

roul_gif <- image_append(c(a_mgif[1], b_mgif[1]),stack=TRUE)
for(i in 2:500){
  combined <- image_append(c(a_mgif[i], b_mgif[i]),stack=TRUE)
  roul_gif <- c(roul_gif, combined)
}

## Save the final file as a .gif file

image_write(roul_gif, "roulette_stacked_point_line_500.gif")
If you are at all familiar with the politics and communication surrounding the global warming issue you’ll almost certainly have come across one of the most popular talking points among those who dismiss (“deny”) contemporary anthropogenic (human-caused) climate change (I’ll call them “climate deniers” henceforth). The claim goes something like this:
“If scientists can’t predict the weather a week from now, how in the world can climate scientists predict what the ‘weather’ [sic!] is going to be like 10, 20, or 50 years from now?”
Notably, the statement does possess a prima facie (i.e., “commonsensical”) claim to plausibility–most people would agree that it is easier (other things being equal) to make predictions about things are closer in time to the present than things that happen well into the future. We have a fairly good idea of the chances that the Vancouver Canucks will win at least half of their games for the remainder of the month of March 2021. We have much less knowledge of how likely the Canucks will be to win at least half their games in February 2022, February 2025, or February 2040.
Notwithstanding the preceding, the problem with this denialist argument is that it relies on a fundamental misunderstanding of the difference between climate and weather. Here is an extended excerpt from the US NOAA:
We hear about weather and climate all of the time. Most of us check the local weather forecast to plan our days. And climate change is certainly a “hot” topic in the news. There is, however, still a lot of confusion over the difference between the two.
Think about it this way: Climate is what you expect, weather is what you get.
Weather is what you see outside on any particular day. So, for example, it may be 75° degrees and sunny or it could be 20° degrees with heavy snow. That’s the weather.
Climate is the average of that weather. For example, you can expect snow in the Northeast [USA] in January or for it to be hot and humid in the Southeast [USA] in July. This is climate. The climate record also includes extreme values such as record high temperatures or record amounts of rainfall. If you’ve ever heard your local weather person say “today we hit a record high for this day,” she is talking about climate records.
So when we are talking about climate change, we are talking about changes in long-term averages of daily weather. In most places, weather can change from minute-to-minute, hour-to-hour, day-to-day, and season-to-season. Climate, however, is the average of weather over time and space.
The important message to take from this is that while the weather can be very unpredictable, even at time-horizons of only hours, or minutes, the climate (long-term averages of weather) is remarkably stable over time (assuming the absence of important exogenous events like major volcanic eruptions, for example).
Although weather forecasting has become more accurate over time with the advance of meteorological science, there is still a massive amount of randomness that affects weather models. The difference between a major snowstorm, or clear blue skies with sun, could literally be a slight difference in air pressure, or wind direction/speed, etc. But, once these daily, or hourly, deviations from the expected are averaged out over the course of a year, the global mean annual temperature is remarkably stable from year-to-year. And it is an unprecedentedly rapid increase in mean annual global temperatures over the last 250 years or so that is the source of climate scientists’ claims that the earth’s temperature is rising and, indeed, is currently higher than at any point since the beginning of human civilization some 10,000 years ago.
Although the temperature at any point and place on earth in a typical year can vary from as high as the mid-50s degrees Celsius to as low as the -80s degrees Celsius (a range of some 130 degrees Celsius) the difference in the global mean annual temperature between 2018 and 2019 was only 0.14 degrees Celsius. That incorporates all of the polar vortexes, droughts, etc., over the course of a year. That is remarkably stable. And it’s not a surprise that global mean annual temperatures tend to be stable, given the nature of the earth’s energy system, and the concept of earth’s energy budget.
In the same way that earth’s mean annual temperatures tend to be very stable (accompanied by dramatic inter-temporal and inter-spatial variation), we can see that the collective result of many repeated spins of a roulette wheel is analogously stable (with similarly dramatic between-spin variation).
A roulette wheel has 38 numbered slots–36 of which are split evenly between red slots and black slots–numbered from 1 through 36–and (in North America) two green slots which are numbered 0, and 00. It is impossible to determine with any level of accuracy the precise number that will turn up on any given spin of the roulette wheel. But, we know that for a standard North American roulette wheel, over time the number of black slots that turn up will be equal to the number of red slots that turn up, with the green slots turning up about 1/9 as often as either red or black. Thus, while we have no way of knowing exactly what the next spin of the roulette wheel will be (which is a good thing for the casino’s owners), we can accurately predict the “mean outcome” of thousands of spins, and get quite close to the actual results (which is also a good thing for the casino owners and the reason that they continue to offer the game to their clients).
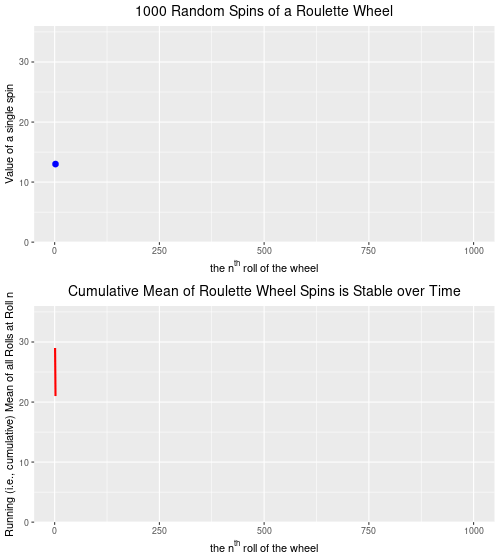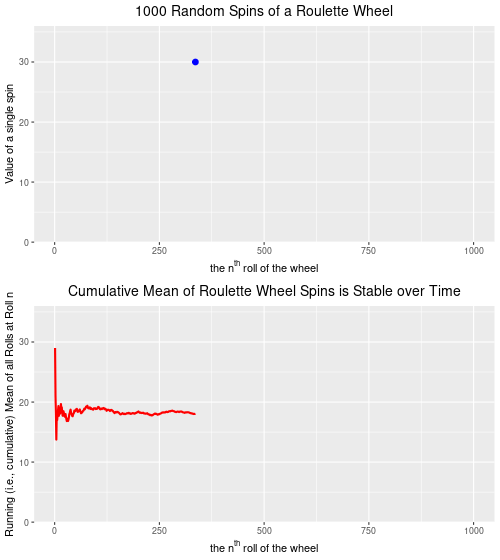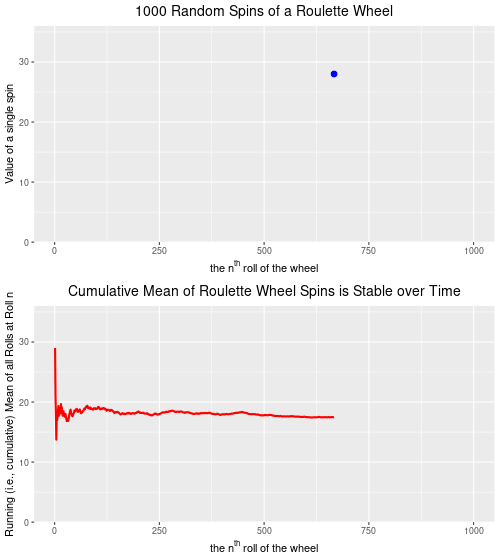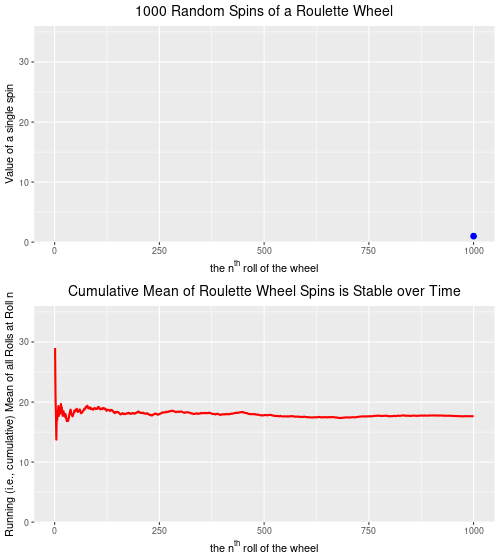
Below are two plots–the upper plot is an animated plot of each of 1000 simulated random spins of a roulette wheel. We can see that the value of each of the individual spins varies considerably–from a low of 0 to a high of 36. It is impossible to predict what the value of the next spin will be.
The lower plot, on the other hand is an animated plot, the line of which represents the cumulative (i.e. “running”) mean of 1000 random spins of a roulette wheel. We see that for the first few random rolls of the roulette wheel the cumulative mean is relatively unstable, but as the number of rolls increases the cumulative mean eventually settles down to a value that is very close to the ‘expected value’ (on a North Amercian roulette wheel) of 17.526. The expected value* is simply the sum of all of the individual values 0,0, 1 through 36 divided by the total number of slots, which is 38. Over time, as we spin and spin the roulette wheel, the values from spin-to-spin may be dramatically different. Over time, though, the mean value of these spins will converge on the expected value of 17.526. From the chart below, we see that this is the case.
Created by Josip Dasović
Completing the analogy to weather (and climate) prediction, on any given spin our ability to predict what the next spin of the roulette wheel will be is very low. [The analogy isn’t perfect because we are a bit more confident in our weather predictions given that the process is not completely random–it will be more likely to be cold and to snow in the winter, for example.] But, over time, we can predict with a high degree of accuracy that the mean of all spins will be very close to 17.526. So, our inability to predict short-term events accurately does not mean that we are not able to predict long-term events accurately. We can, and we do. In roulette, and for the climate as well.
TLDR: Just because a science can’t predict something short-term does not mean that it isn’t a science. Google quantum physics and randomness and you’ll understand what Einstein was referring to when he quipped that “God does not play dice.” Maybe she’s a roulette player instead?
Note: This is not the same as the expected dollar value of a bet given that casinos generate pay-off matrixes that are advantageous to themselves.
We used the last session of IS450 as a chance to hold a mock United Nations climate conference simulation. The participants brought forward many intriguing and instructive topics, and I applaud them for putting in the time and energy to make the simulation as successful as I, at least, judged it to be. At some point during the proceedings, there was majority agreement (finally!) on one small element of the overall framework resolution. Interestingly, though, immediately upon the successful passing of that small piece of the framework a couple of delegates put forward a motion to make the obligations legally binding. A heated discussion ensued debating the merits and disadvantages of such an approach.
In the current round of UNFCCC climate negotiations, behind held in Lima, Peru, Nicholas Stern (author of the well-known Stern Review Report on the Economics of Climate Change) has argued against making international climate treaty obligations legally binding. What is Lord Stern’s rationale for this?
“Some may fear that commitments that are not internationally legally-binding may lack credibility,” he said.
“That, in my view, is a serious mistake. The sanctions available under the Kyoto Protocol, for example, were notionally legally-binding but were simply not credible and failed to guarantee domestic implementation of commitments.”
In Lima, negotiators are trying to hammer out the format that mitigation efforts should take. By the end of March next year countries have to declare their hands, but they have yet to formalize what will be included in these commitments and what will not.
Lord Stern believes that grounding the process in the laws and promises that countries undertake by themselves is a better model for a deal than a top-down process like Kyoto.
“It will be enforceable and deliverable through the arrangements and laws in the countries themselves.
“That way you will get stronger ambition as countries won’t be tempted to be hesitant about some type of international sanction.”
What do you think about Lord Stern argument? Would you support voluntary obligations over mandatory ones?
Here is an interview with Lord Stern from earlier this week in Lima, wherein he speaks on the link between economic growth, development, and better climate responsibility?
Host Peter Mansbridge, of the Canadian Broadcasting Coroporation’s (CBC) evening news program, The National, interviewed United Nations Secretary-General Ban Ki-Moon earlier this week on issues related to climate change and the Alberta oil sands. (I’ll have more next week about the anti-pipeline protests on Burnaby Mountain (in the vicinity of SFU) next week.)
Here are some excerpts:
Ban Ki-Moon: I know the domestic politics in Canada and Australia…but this is a global issue.
Peter Mansbridge: But the Canadian argument has always been, if everybody’s not in, we’re not in. [This obviously refers to the Kyoto Protocol’s division of countries into those that are required to make cuts (so-called Annex I countries) and those (mostly ‘developing’ countries) that do not.]
Ban Ki-Moon: China and [the] United States have taken such a bold initiative, Germany has been a leading country now, and [in] the European Union, twenty-eight countries have shown solidarity and unity. Therefore, it is only natural that Canada as one of the G-7 countries should take a leadership role.
The Secretary-General also spoke about the Alberta oil sands, which have been in the news lately in our part of the world as the result of protests aimed at Kinder Morgan over its plans to increase (three-fold) the flow of tar sands oil (bitumen) through an existing pipeline that runs through Burnaby Mountain to waiting oil tankers in Vancouver’s Burrard Inlet, to almost one million barrels per day.
Peter Mansbridge: Should Canadians, or the Canadian government, look beyond the oil sands to make its decisions about climate change?
Ban Ki-Moon: Energy is a very important, this is a cross-cutting issue. There are ways to make transformative changes from a fossil fuel-based economy to a climate-resilient economy by investing wisely in renewable energy resources.
Peter Manbridge: So back away from…
Ban Ki-Moon: Yes, Canada is an advanced economic country…you have many technological innovations, so with the technological innovation and financial capacity, you have many ways to make some transformative changes.
This is the key; the political and societal will has to be created and sustained to force our leaders to make the requisite changes, which will move our country towards an economy that is climate-resilient. An economically-sustainable future and economic well-being are not mutually exclusive. Indeed, there is every reason to believe that not not only are they not mutually exclusive, but that that each is necessary for the other. If we don’t start moving away from our “extractivist economic structure”, we in Canada face the prospect of a future with tremendous ecological and environmental degradation coupled with economic despair, when our leaders finally realize that rather than using our current wealth to innovate away from the extraction and toward energy innovation, we have squandered our wealth on fining ever cheaper ways to dig up crap that the world no longer wants to buy.
“Polluted and poor”–how’s that for a political campaign slogan?
This blog is back from an end-of-semester-induced slumber with some important posts. Here is post, the first:
Here’s an intriguing map, posted on the spatialities.com web site. It shows what Vancouver would look like with an expected 80-meter sea-level rise, which is what the United States Geological Survey predicts would happen were the Antarctic and Greenland ice sheets to melt completely (remember that these are land-based ice sheets).
Most of the current global land ice mass is located in the Antarctic and Greenland ice sheets (table 1). Complete melting of these ice sheets could lead to a sea-level rise of about 80 meters, whereas melting of all other glaciers could lead to a sea-level rise of only one-half meter.
Don’t go and sell your Fairview condo just yet, however, as this scenario is not projected to complete for between 1,000 and 10,000 years. Of course, this is a process that develops incrementally (though not linearly) over time and the city would be deeply affected adversely with only a fraction of that projected rise in sea levels.
For those who may doubt that the world’s glaciers are melting, here is video of the largest glacier ‘calving’ event ever caught on film. The end of the clip demonstrates the extent of change in the rate of melting and glacial retreat over the last century. Just watch!




 Clouds, Clocks, and Sitting at Tables

You must be logged in to post a comment.